1st Place
Kube SRE Gym
Kube SRE Gym is a self-improving RL environment where a small language model (Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents from scratch.
Core trick
GRPO trains a small model against a live Kubernetes cluster, with reward from fault-fix outcomes plus an LLM judge scoring SRE workflow quality.
Description
Kube SRE Gym is a self-improving RL environment where a small language model
(Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents
from scratch. The agent interacts with a live GKE cluster via kubectl commands
— OOMKills, CrashLoopBackOffs, and ImagePullBackOffs are real Kubernetes
events, not simulations. An adversarial designer (Claude) creates targeted
incidents based on the agent's tracked weaknesses, while a curriculum
controller escalates difficulty as mastery improves. Training uses GRPO (TRL
0.29.0 + vLLM) with an LLM judge that scores SRE workflow quality using three
expert personas (Junior/Senior/Principal). Within 8 episodes, the agent
learned to discover cluster topology, identify fault types from pod status,
and apply correct fixes — all from reward signal alone, with zero hardcoded
knowledge of the cluster.
README excerpt
--- title: Kube SRE Gym emoji: 🔧 colorFrom: red colorTo: yellow sdk: docker pinned: false app_port: 8000 base_path: /web tags: - openenv --- # Kube SRE Gym ### Can a 0.6B model learn to be an on-call SRE — from scratch? We gave a tiny language model a pager, a live Kubernetes cluster, and zero knowledge of what a pod even is. No pre-training on DevOps docs. No few-shot examples. Just a PagerDuty alert and a `kubectl` prompt. Within 8 episodes, it learned to discover namespaces, read pod statuses, identify OOMKills from CrashLoopBackOffs, and apply the correct fix. By episode 4, it was resolving incidents faster than our hand-written baselines. **This is Kube SRE Gym** — a self-improving environment where an RL agent learns to diagnose and fix real production Kubernetes failures through adversarial self-play, curriculum-driven difficulty, and GRPO. > **1st Place, OpenEnv Hackathon** (PyTorch + Cerebral Valley, $15K prize) | Built with [OpenEnv v0.2.1](https://github.com/meta-pytorch/OpenEnv/tree/v0.2.1) | Deployed on [HF Spaces](https://huggingface.co/spaces/openenv-community/kube-sre-gym) | Training via [HF TRL](https://github.com/huggingface/trl) in [Colab](kube_sre_gym_colab.ipynb) [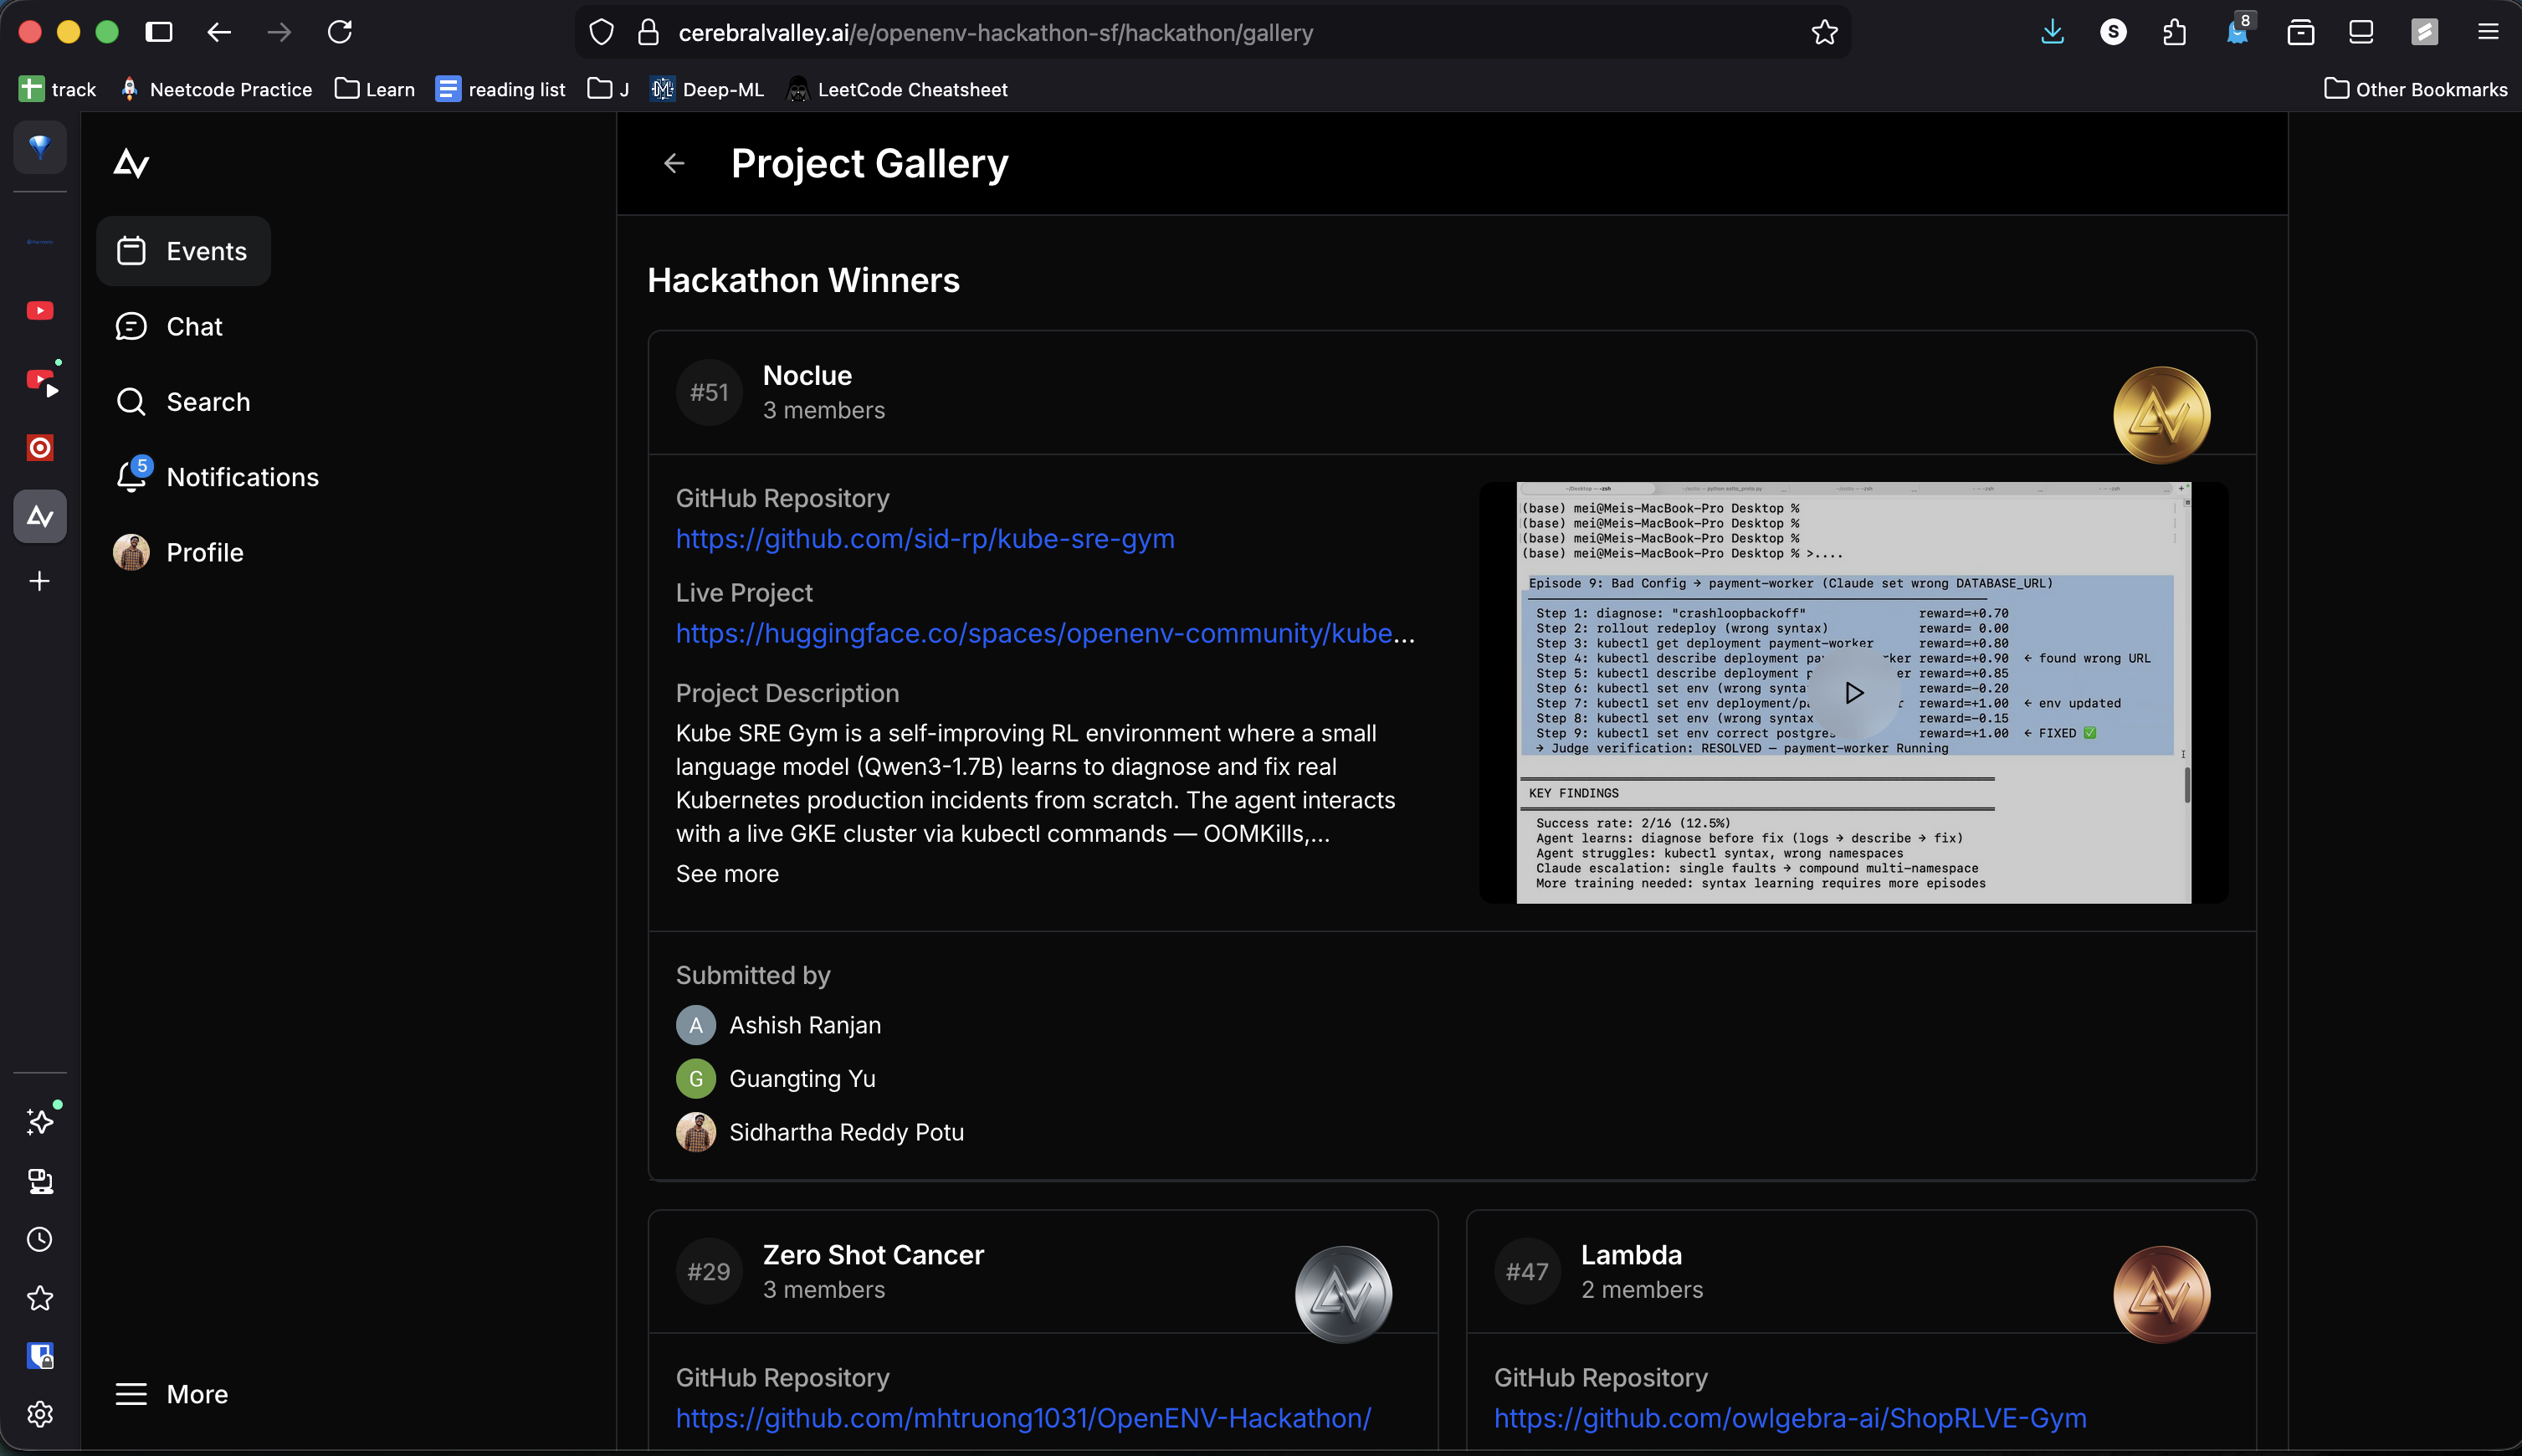](https://cerebralvalley.ai/e/openenv-hackathon-sf/hackathon/gallery) --- ## The Story: From Blind to On-Call ### Act 1: The Cold Start Episode 1. The agent receives its first